Most AI apps send every small decision to a large language model: route this request, which tool to call, is the task done. Each call costs tokens and can answer differently next time. Put that in an agent loop and the bill grows faster than the results.
Here, code runs the workflow. AI handles only the judgments code can't make, and returns typed answers your program uses directly: a pick from a list, a score, a yes or no with a probability. Jev, TypeSafe's decision model, is our main tool. Claude and other LLMs come in when generating text or code is the job.
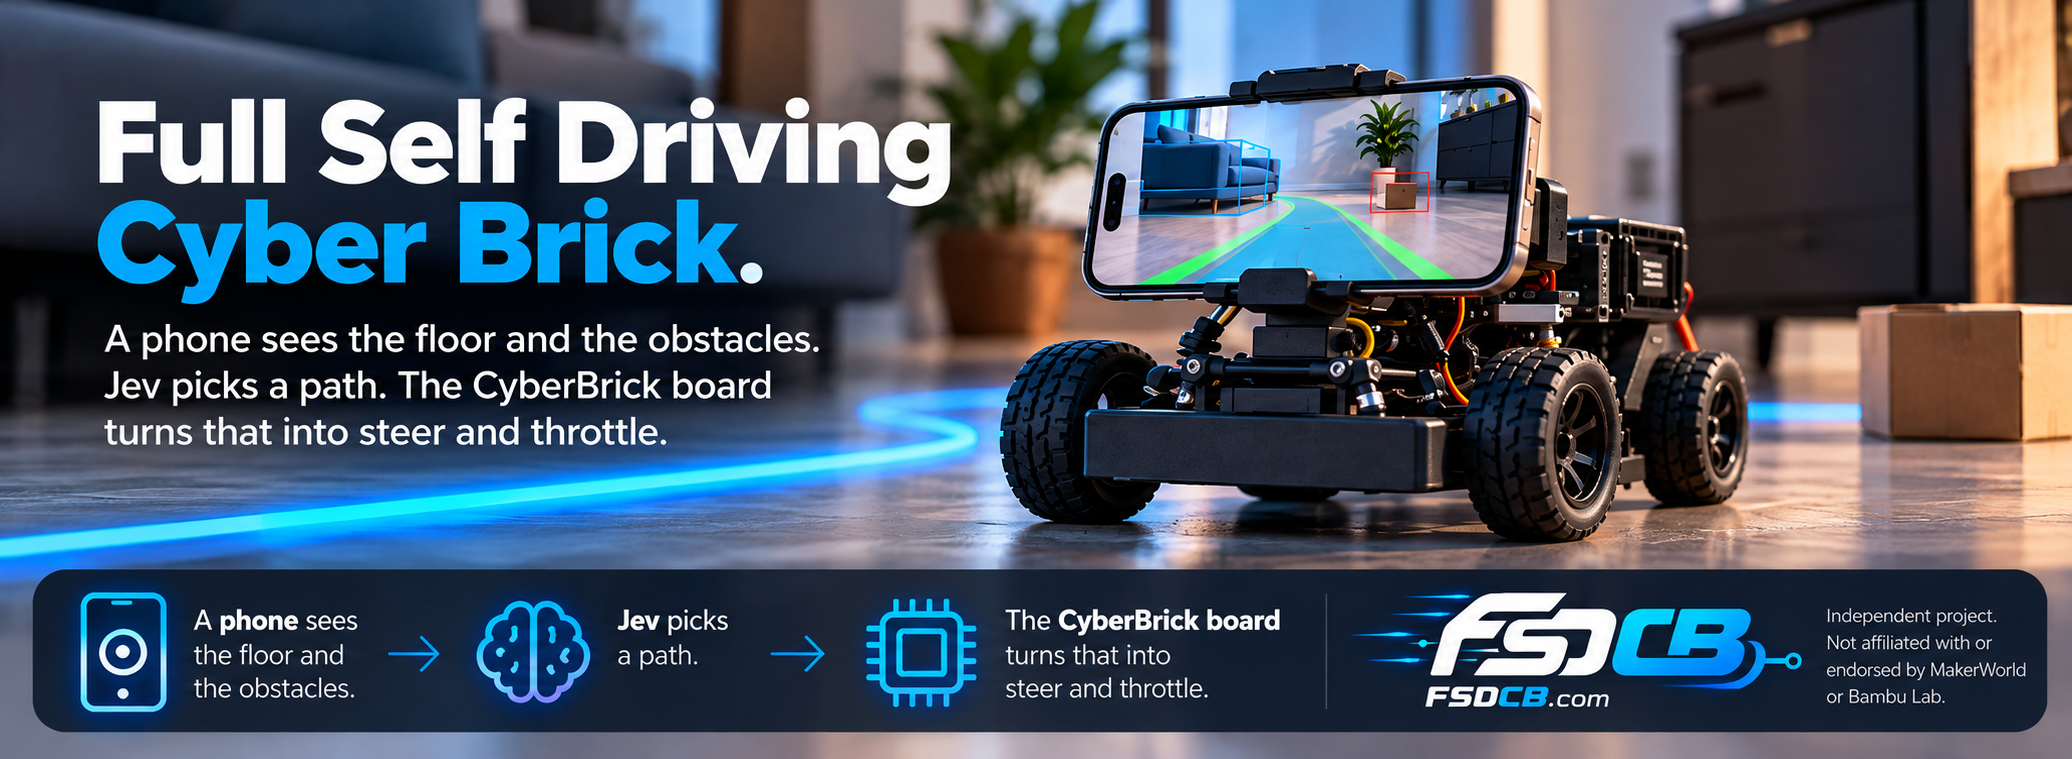
The chassis is a Bambu Lab CyberBrick Ultimate kit. The phone is the whole perception unit. It samples candidate arcs, drops the ones that would hit something, and asks Jev which arc to take. The ESP32 receives steer and throttle over UDP and brakes on its own if the phone goes quiet.
The receiver app is in the repo. It has not been put on the car yet. The decision loop and the UDP protocol are written down. Next is a bench test of the receiver, then the phone app.
Links
Inspiration
JevPilotThe simulator this decision loop is modeled on.